RAG and a vector database are not competing technologies. RAG, or retrieval-augmented generation, is an application architecture that retrieves relevant information before an LLM produces an answer. A vector database is one possible way to retrieve semantically similar information inside that architecture.
Put simply: RAG answers questions using external knowledge; a vector database helps find information by meaning rather than exact wording. You can build RAG without a dedicated vector database, and you can use a vector database without building a chatbot or using an LLM. Neither is automatically the right answer for structured business data.
RAG vs vector database: the short answer
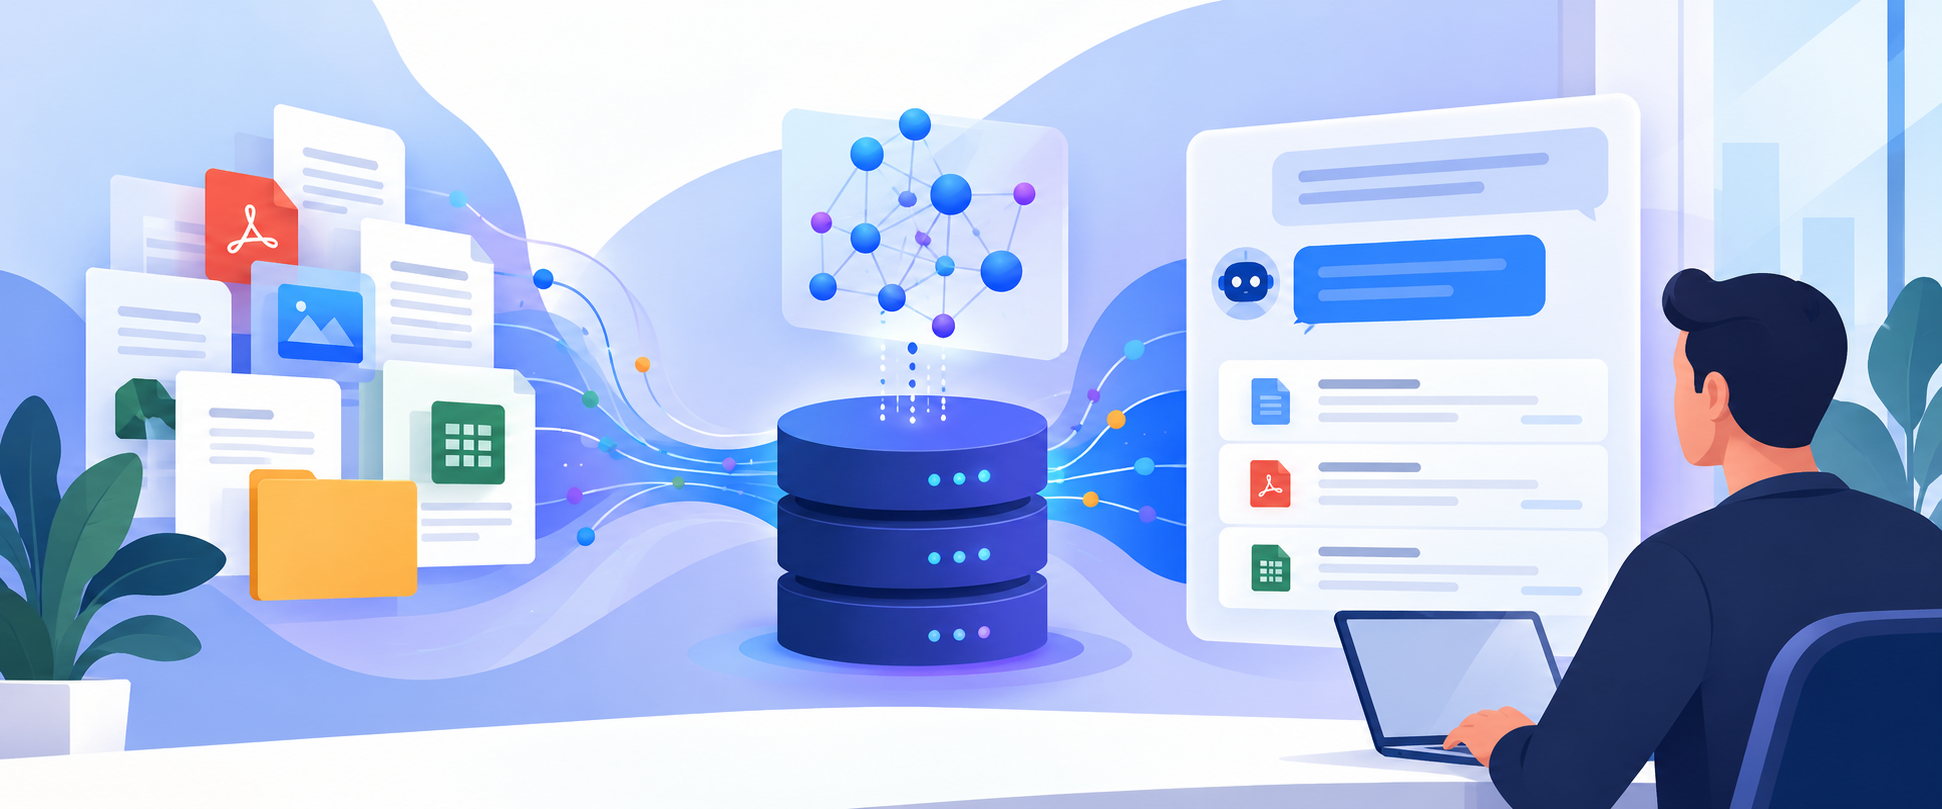
The confusion is understandable because a common RAG diagram is documents → chunks → embeddings → vector database → retrieved context → LLM → answer. That is one valid implementation, but it is not the whole system and it is not the only design.
A production-ready system is closer to source systems → extraction, OCR, cleanup and deduplication → metadata, authority, version and permissions → SQL, keyword, vector or hybrid retrieval → filtered source selection → answer with citations, controls and fallback behaviour → evaluation, monitoring and re-indexing. The database is only one part of the retrieval layer. That operational discipline is consistent with Google Cloud's MLOps guidance on testing, deployment and monitoring throughout the lifecycle.
What is RAG?
RAG stands for retrieval-augmented generation. It gives an LLM relevant external information when a user asks a question. Rather than relying only on what the model learned during training, the system retrieves approved sources and supplies that context with the prompt. For a fuller introduction to the workflow, see our guide to what a RAG pipeline is; for implementation patterns around application boundaries, permissions and workflow integration, see how to integrate an LLM into existing software.
For example, an employee might ask, ‘What are our obligations when this regulatory condition occurs?’ A RAG system can search approved regulations, policy documents, case files, guidance and internal records; select relevant passages; then produce an answer that cites the underlying sources.
RAG is useful when knowledge changes frequently, exists across many documents, needs citations, is too specific for a general-purpose model, or must be controlled by permissions and tenant boundaries. It does not guarantee correctness. It gives a system a better chance of using current evidence only when retrieval, source governance and evaluation are designed properly.
What is a vector database?
A vector database stores and searches numerical representations of content called vectors, commonly created through embeddings. An embedding represents aspects of a phrase, paragraph, image or other item in a form that can be compared mathematically. That enables semantic search: finding content with similar meaning even when it does not use the same words. For example, pgvector's official documentation describes vector similarity search as a PostgreSQL extension rather than a separate RAG product.
A user may ask, ‘Which documents explain our obligations when this condition happens?’ The source document may use different wording altogether. Exact-keyword search can miss that result; semantic retrieval can identify that the concepts are related.
But a vector database does not know whether a document is authoritative, current, permitted for the user or legally applicable. Those decisions belong to the broader application, using metadata, filtering, source governance and retrieval logic.
A vector database is useful, but it is not the entire RAG system
The most dangerous simplification in AI architecture is treating vector similarity as truth. A highly similar result can still be wrong because it is an obsolete policy, an unapproved draft, written for another jurisdiction, restricted to another tenant, based on poor OCR, or missing the context that changes its meaning.
A better retrieval model is semantic relevance + metadata + authority + version + permissions. Semantic similarity is useful evidence. It is not authority.
A production lesson: document quality beats model swapping
In one legal and compliance document-assistant project, the knowledge base contained more than 50,000 documents and records: contracts, case files, regulations, regulatory guidance, scanned PDFs, client records, and other structured and unstructured material. The problem was not simply how to put the documents into an LLM. Lawyers and staff needed to find the right information without guessing the terminology used inside a document.
Semantic retrieval was justified because users searched for meaning, not just strings. But the production work extended far beyond a vector index: document extraction and OCR, cleaning and deduplication, document and version metadata, permissions, filtering, citations, source verification, and stale or conflicting-document handling.
The project produced an approximate 60–70% reduction in research and search time; some searches that had taken around 20 minutes could be completed in under five. The more important lesson was why it worked: retrieval was treated as a governed knowledge problem rather than a model-selection exercise.
Consider four files: Policy.pdf, Policy-Final.pdf, Policy-Final-v2.pdf and Policy-Approved.pdf. Embedding all four without version metadata can surface a relevant but superseded answer. The vector search did its job. The system still failed because it could not identify the authoritative source.
When you need RAG, a vector database, both, or neither
Use SQL or APIs for structured facts
If the answer already exists as a reliable structured field, SQL or an API is usually more accurate and easier to govern. ‘Show all failed invoices submitted this month’ is a database query, not a semantic-search problem. In an e-invoicing system, invoice numbers, submission status, dates, tax values, product records and FBR responses should be retrieved deterministically rather than inferred from embeddings.
Use conventional search when exact words matter
Keyword or lexical search is often better for invoice IDs, legal-section references, product codes, names, SKUs, exact titles, error codes and known phrases. Semantic retrieval can understand conceptual similarity, but it may underperform when an exact identifier is the primary signal. PostgreSQL's full-text-search documentation is a useful reference when evaluating conventional search alongside semantic retrieval.
Use vector search when meaning matters more than exact wording
Vector retrieval is useful when a user’s wording may differ substantially from the source material and the answer sits in unstructured content. Common examples include policy questions, document assistants, support knowledge bases, research repositories, contracts, compliance material and internal operational guidance.
Use hybrid retrieval when exact terms and meaning both matter
Many real systems need both. A legal researcher may need a specific regulation number and a conceptual explanation. A support user may name an exact product while describing a problem in their own words. Hybrid retrieval combines lexical matching with semantic similarity and is often more robust than assuming either method should win every time.
Use RAG only when generated answers add value
Retrieval does not always need generation. If users need a ranked list of documents, a well-designed search interface may be better than a chatbot. If a workflow needs an exact account balance, query results may be enough. Before adding RAG, ask whether the user needs an LLM-generated explanation or simply a reliable result.
Do you need a dedicated vector database?
Not necessarily. For moderate semantic-search requirements, especially when an application already uses PostgreSQL, pgvector can keep relational metadata, permissions, operational data and embeddings close together. A dedicated vector database becomes more attractive when semantic retrieval is a significant subsystem with large collections, heavier workloads, specialised filtering or ranking needs, and independent scaling requirements.
The decision should not be driven by a fashionable architecture diagram. It should be driven by the requirements your product must satisfy. For an implementation budget perspective, read our breakdown of RAG pipeline development cost, including the engineering work around data preparation, permissions, evaluation and operations.
Do you actually need a vector database?
- Is the answer a structured fact in a database or API? Use SQL or API retrieval first.
- Does exact wording, an identifier, a product code or a known phrase matter most? Start with lexical search.
- Is the user locating unstructured information by concept or meaning? Consider embeddings and semantic retrieval.
- Do exact terminology and semantic meaning both matter? Consider hybrid search.
- Does knowledge change frequently? Prefer retrieval and re-indexing over baking the information into a model.
- Does the user need an LLM-generated explanation or summary? If not, stop before adding RAG.
- Can you enforce authority, versioning, permissions and evaluation? If not, solve those requirements first.
RAG vs fine-tuning: a related decision
RAG and fine-tuning solve different problems. RAG handles changing knowledge; fine-tuning or behavioural optimisation handles how the model behaves. If a policy changes tomorrow, update the approved source and re-index it. Do not retrain a model every time a document changes. Our detailed RAG vs fine-tuning comparison explains when teams use each approach together.
Fine-tuning can help with consistent behaviour, format, tone, classification or structured output. It is not usually the first choice for keeping a large and changing document corpus current.
The production details generic RAG articles leave out
- Source quality and OCR: poor scans can alter names, numbers, dates and clauses before retrieval even begins.
- Metadata and authority: tenant, department, jurisdiction, effective date, version, approval status and confidentiality determine whether a source is usable.
- Chunking: a fixed chunk size can work for FAQs and destroy meaning in legal clauses, tables or technical procedures.
- Re-indexing: teams need rules for old embeddings, approved updates, partial ingestion failures and stale-content reporting.
- Permissions: filters must be applied before retrieved context reaches the model, especially in multi-tenant or sensitive environments; the OWASP Top 10 for LLM Applications is a useful security baseline.
- Evaluation: measure retrieval quality, context relevance and final-answer accuracy separately so the real failure can be fixed.
Common misconceptions
- ‘A vector database makes the model knowledgeable about our documents.’ No. It only helps find potentially relevant material.
- ‘We should fine-tune the model on all company documents.’ Usually not when the information changes regularly.
- ‘RAG eliminates hallucinations.’ No. It can still retrieve an obsolete source, use corrupt OCR, lack context or ignore evidence.
- ‘Embeddings replace normal search.’ Not always. Exact identifiers and references often need lexical or structured retrieval.
- ‘Every AI application needs a vector database.’ No. SQL, APIs, conventional search, hybrid retrieval or no AI layer may be the better answer.
The practical takeaway
Start with the business question, not the technology. ‘How many leave days does employee 147 have remaining?’ should come from an HR system. ‘Explain our leave policy for employees working across two jurisdictions’ may suit a governed RAG system. ‘Find every invoice that failed with this error code’ needs structured or lexical search. ‘Show documents that discuss the operational effect of this policy change’ may benefit from semantic or hybrid retrieval.
The architecture should reflect the knowledge problem, not the popularity of the technology. A vector database is valuable when it solves a real semantic-retrieval need. It is not a shortcut around source quality, governance or product judgement. The NIST AI Risk Management Framework is a helpful external reference for treating trustworthiness and evaluation as operating requirements, not final-stage checks. For more on turning those controls into a reliable system, read how to build a production-ready ML model.
Frequently asked questions
Is RAG the same as a vector database?
No. RAG is an architecture that retrieves information before an LLM generates an answer. A vector database is one optional tool for semantic retrieval within that architecture.
Can I build RAG without a vector database?
Yes. RAG can use SQL queries, APIs, conventional search, hybrid search, file retrieval or other retrieval methods. The best choice depends on the data and the user task.
When is SQL better than RAG?
SQL is better when the answer is a structured, deterministic fact such as a status, date, count, balance, ID or validated transactional record.
Does RAG stop hallucinations?
No. RAG can reduce unsupported answers when retrieval and evaluation are well designed, but source quality, authority, versioning, permissions and citations still matter.
If you are assessing a document assistant, semantic-search feature or governed RAG workflow, our AI/ML development services can help define the smallest architecture that meets the real retrieval, security and operating requirements.